The co-designed chips and networking inside Rubin
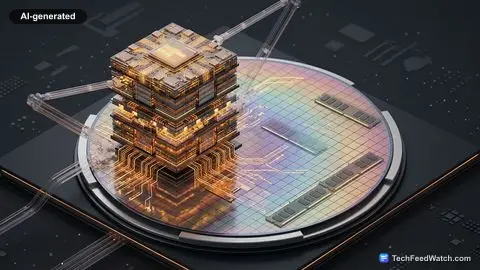
The NVIDIA Rubin platform is proof of co-design principles, where every component is developed in conjunction with others to ensure maximum synergy and performance. At its core, the platform features the Rubin GPU, designed specifically for intensive AI workloads, alongside the Vera CPU, which handles general-purpose computing and orchestrates the entire system.
Data movement within and between these powerful processing units is critical for AI performance. The Rubin platform utilizes NVLink 6, the next iteration of NVIDIA’s high-speed interconnect technology, to provide immense bandwidth, exceeding 260TB/s across the system.
This level of interconnectivity allows GPUs and CPUs to exchange data at speeds previously unattainable, minimizing bottlenecks that often plague large-scale AI training and inference.
The importance of memory technology in NVIDIA AI chips is consistently highlighted by the industry, as memory bandwidth and capacity are as critical as raw compute power. NVIDIA AI Chips: Why Memory Technology Is Their Secret Weapon underscores this point.
Beyond the core processors and interconnects, the platform integrates specialized networking hardware. The BlueField-4 DPU (Data Processing Unit) offloads network and storage processing from the CPUs, enhancing overall system efficiency and security.
Complementing this is the ConnectX-9 SuperNIC, a high-performance network interface card, and Spectrum networking solutions, which collectively provide the solid, high-bandwidth communication fabric necessary for a distributed AI factory. This comprehensive integration of specialized components ensures that the entire system functions as one massive, optimized unit, rather than a collection of disparate parts.
For instance, the Rubin GPU is engineered to deliver up to 50 petaflops of AI inference power and comes equipped with 288GB of HBM4 memory per GPU.
When scaled up, an NVL72 rack, a critical building block of the Rubin infrastructure, can achieve 3.6 exaflops of compute. This illustrates the platform’s capability to deliver unprecedented levels of computational power, critical for the increasingly complex demands of modern AI models.
How Rubin cuts inference costs and scales deployment
The NVIDIA Rubin platform signifies a profound shift in how AI infrastructure is conceived and deployed. Traditionally, organizations might purchase GPUs, CPUs, and networking equipment separately, then integrate them.
The Rubin platform’s co-designed, “AI factory” approach streamlines this, offering a ready-made, optimized solution that reduces complexity and accelerates deployment for AI developers. This integrated design aims to lower operational overhead and deliver immediate performance benefits.
The impact on AI development is substantial. For large-scale AI inference, a key phase where trained models are used to make predictions or decisions, the Rubin platform promises significant cost reductions.
As Evolving AI points out, NVIDIA claims up to 10x lower AI inference costs than the prior Blackwell generation. This dramatic reduction in cost per inference can democratize access to advanced AI capabilities, making it more economically feasible for a wider range of applications and industries.
The sheer computational power and memory capacity, such as 288GB of HBM4 memory per GPU, enable the training and deployment of much larger and more sophisticated AI models. This directly impacts the capabilities of AI, allowing for more nuanced understanding, complex problem-solving, and higher-fidelity outputs across various domains.
The adoption of such advanced platforms underpins the growth of the overall AI compute ecosystem. What NVIDIA GTC Means for Its AI Compute Ecosystem Strategy highlights this strategic vision.
Leading AI companies are already recognizing these advantages. Companies like Microsoft, OpenAI, Anthropic, Meta, xAI, Google, AWS, Oracle, and CoreWeave are actively adopting the Rubin platform. This widespread adoption by industry leaders underscores the platform’s perceived value and its potential to become the standard for high-performance AI infrastructure.
Their investment signals a collective belief that this integrated factory approach is the path forward for manufacturing intelligence. How Do You Deploy NVIDIA AI Factories at Scale? explains this architectural philosophy in detail.
Vendor lock-in and high upfront infrastructure costs
While the Rubin platform presents significant advancements, its integrated “AI factory” design also implies a strategic commitment that might not be immediately apparent. The move towards a fully co-designed system, while optimizing performance, could also deepen vendor lock-in for organizations.
Relying on a singular, highly integrated platform means that switching vendors or customizing specific components outside of NVIDIA’s ecosystem might become more challenging and costly. This is not a limitation of Rubin itself but an inherent characteristic of highly integrated, proprietary solutions.
Deploying a “massive AI infrastructure platform” like Rubin demands substantial capital expenditure and specialized operational expertise. While the platform promises lower inference costs over time, the initial investment required for the hardware and the specialized data center infrastructure to support 3.6 exaflops of compute per NVL72 rack could be prohibitive for smaller entities.
The focus on scale suggests that its immediate impact will primarily be felt by hyperscalers, large enterprises, and well-funded AI research organizations. The benefits of 10x lower AI inference costs are most realized when operating at immense scale, where the cumulative savings outweigh the initial infrastructure investment.
Another aspect often overlooked is the continued pressure on supply chains. Producing complex, integrated systems with cutting-edge components like HBM4 memory requires a sophisticated and resilient manufacturing process. Any disruptions could significantly impact availability and adoption timelines, affecting the very companies eager to deploy these AI factories.
Why Rubin sets a new benchmark for AI infrastructure
The NVIDIA Rubin platform represents more than just an incremental upgrade in AI hardware; it embodies a fundamental architectural shift. By conceptualizing AI infrastructure as an “entire factory built to manufacture intelligence,” NVIDIA moves beyond the traditional component-centric view.
This approach, integrating the Vera CPU, Rubin GPU, and advanced networking like NVLink 6 and BlueField-4 DPU into a coherent whole, is not merely a passing trend but a permanent shift in high-performance AI computing.
The capabilities—such as 50 petaflops of AI inference, 288GB of HBM4 memory, and 3.6 exaflops per NVL72 rack—combined with the promise of up to 10x lower AI inference costs than Blackwell, make a compelling case for its long-term impact.
The rapid adoption by major AI players like Microsoft and OpenAI further validates this trajectory. The Rubin platform establishes a new benchmark for AI infrastructure, signaling an era where integrated, co-designed systems are paramount for scaling artificial intelligence to its next frontier.