How Google TPU Is Used to Run AI Workloads

Based on 6 web sources and a video by Bloomberg Tech. TechFeedWatch is not affiliated with the creator, and all rights to the video remain theirs.

Google designs custom Tensor Processing Units to accelerate the heavy mathematics behind artificial intelligence. These specialized chips handle massive matrix calculations for core services like Search, Translate, and the Gemini models. While Nvidia graphics cards still dominate general software development, TPUs deliver targeted computing power across large cloud data centers.
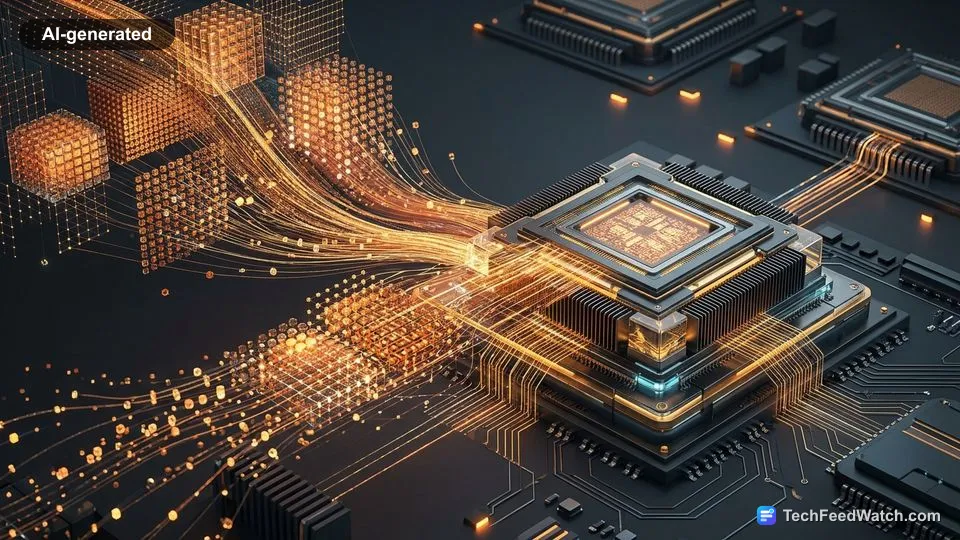
AI-generated illustration: How Google TPU Is Used to Run AI Workloads

A Google Tensor Processing Unit, or TPU, is a specialized computer chip. Engineers designed it to speed up artificial intelligence workloads.

Google uses TPUs to train massive machine learning models (software trained on data). The chips also handle billions of daily user requests across its global web services.

According to Google Cloud Documentation, these custom processors speed up complex matrix mathematics (math using grids of numbers). This math powers modern neural networks (AI systems modeled on the brain).

How does a TPU differ from CPUs and GPUs?

Engineers built it for neural network math rather than general desktop software or computer graphics.

Central processing units (CPUs) handle diverse operating system tasks and switch between programs smoothly. Graphics processing units (GPUs) run thousands of mathematical threads (streams of calculations) at once.

This structure works well for video rendering and experimental AI code. In contrast, TPUs are application-specific integrated circuits, or ASICs (chips built for a single purpose). Engineers stripped them down to perform large-scale matrix operations at high volume.

According to Google Cloud Documentation, software cannot run on a TPU without the Accelerated Linear Algebra (XLA) compiler (a program translating code). The compiler transforms high-level framework graphs from the machine learning frameworks PyTorch or JAX into custom machine code.

Hardware components show clear architectural trade-offs:

  • CPUs prioritize low latency (the delay before data arrives) for general tasks and diverse system operations.
  • GPUs offer flexible parallel compute (simultaneous calculations) suitable for experimental algorithms and rendering graphics.
  • TPUs focus execution units on dense matrix multiplication to maximize data throughput (the volume of data processed).

Watch: the video

4 min video. In the video: Bloomberg Tech on Google’s shift to specialized inference TPUs

Google runs Search, YouTube, and Gemini on TPUs

The hardware processes user data and generates algorithmic predictions at planetary scale.

According to Google Cloud Blog, Google created the TPU in 2013 after reviewing internal data. Forecasts showed that three minutes of daily voice search per Android user would double data center requirements, according to Google Cloud Blog.

Today, TPUs handle live workloads across Google Search ranking, Google Translate, and Google Photos, according to Google Cloud Blog. The company also uses TPUs to serve YouTube recommendations. In addition, Google trains its flagship Gemini generative models on TPUs.

According to Google Cloud Documentation, TPU chips contain dedicated SparseCores. These specialized dataflow processors accelerate recommendation algorithms and sparse mathematical calculations (math involving mostly zero values).

For everyday web users, this hardware shapes daily digital interactions:

  • Search results appear in fractions of a second because TPUs score web page relevance instantly.
  • Video feeds update personal suggestions continuously based on viewing habits.
  • Live translation tools process foreign language text directly within conversational applications.

How do developers and enterprises access Google TPUs?

External developers and enterprises access Google TPUs through cloud infrastructure platforms. They rent virtual computing instances (remote slices of server hardware).

Engineers configure clusters (linked groups of computers) through Google Cloud. This setup lets them run large machine learning experiments without buying physical servers. According to Google Cloud Blog, Google split its eighth-generation hardware in April 2026 into two separate chips.

The platform introduced the TPU 8t for cluster training throughput. It also introduced the TPU 8i for inference tasks (when a trained AI model answers a request), according to Google Cloud Blog.

Software compatibility has historically presented hurdles for teams outside Google. According to PyTorch, Google and Meta introduced TorchTPU in 2025.

This software lets developers run PyTorch programs natively on TPUs using standard Python syntax. That update removed the requirement for custom code rewrites, enabling rapid testing.

Enterprises choose Google Cloud TPUs when they need to process enormous batches of structured training data reliably.

Nvidia GPUs remain preferable for custom code and prototyping

Nvidia GPUs remain preferable when developers need broad software compatibility, custom hardware operations, or rapid prototyping cycles (early product testing).

According to Google Cloud Documentation, GPUs and CPUs are better choices for workloads that rely on custom C++ operations not supported by XLA. Workloads bottlenecked by host network speeds or input-output data storage also gain little advantage from TPU architecture, according to Google Cloud Documentation.

Nvidia benefits from its ubiquitous CUDA software ecosystem (a programming framework for Nvidia chips). CUDA supports almost every experimental AI architecture right out of the box. Teams writing brand-new neural network layers often hit compilation errors when trying to run unvetted code through specialized TPU compilers.

Bloomberg Tech on Google’s shift to specialized inference TPUs

Bloomberg Tech reports that surging artificial intelligence usage is driving Google to develop separate chips dedicated entirely to running trained models.

Bloomberg Tech notes that inference demand has grown rapidly enough to make workload specialization sensible. The outlet reports that Google previously combined training and inference tasks onto a single chip architecture.

Bloomberg Tech reports that two key developments drove recent interest in TPUs: external enterprise deals and the public release of Gemini. According to Bloomberg Tech, Meta signed a multibillion-dollar, multiyear agreement to use Google TPUs. Financial firm Citadel is also set to present its TPU deployment at the Google Next conference, Bloomberg Tech reports.

Bloomberg Tech explains that Google tests hardware against internal demands. These include reinforcement learning (an AI training method based on trial and error) workloads where early TPU utilization was too low.

The outlet emphasizes that Google’s Gemini models run training and inference on TPUs. This setup gives engineers immediate operational feedback to refine future hardware.


Frequently Asked Questions

What is a Google TPU chip?

According to Google Cloud Documentation, a Google TPU chip is a custom application-specific integrated circuit built specifically to run machine learning calculations dominated by large matrix math. It accelerates both the training of artificial intelligence and the generation of live model responses.

What is Google TPU architecture?

According to Google Cloud Documentation, TPU architecture features specialized dataflow processors called SparseCores that speed up recommendation models and sparse mathematical operations. The hardware executes instructions generated by the Accelerated Linear Algebra compiler.

What is a Google Tensor Processing Unit used for on edge hardware?

According to Wikipedia, Google produces an Edge TPU for Coral hardware that executes 4 trillion operations per second at 2 watts of power consumption. This compact processor runs local artificial intelligence inferencing directly inside robotics and embedded equipment.

Sources

Jacob S. Olsen

Jacob S. Olsen

Runs TechFeedWatch, from Denmark

How this article was made: it starts from a question people search for on Google. A language model researches that question with Google Search and keeps only facts backed by the pages Google cites — every number names its source, and the 6 sources are listed above. A video from an independent creator on the subject adds one section and is credited on this page. Automatic checks reject drafts with unsourced numbers, one-sided claims or promotion. It publishes automatically — I do not read every article before it goes live. The image at the top is AI-generated and labelled as such.

What is mine is the machinery and the rules it follows: which subjects, which sources, what gets rejected, and what this site is allowed to claim. More on that here — and if something is wrong, tell me.